Vendor Evaluation Criteria for Post-Deploy Verification When Agentic Pipelines Own Your Release Cadence
How to choose post-deploy verification vendors for AI-generated code pipelines.
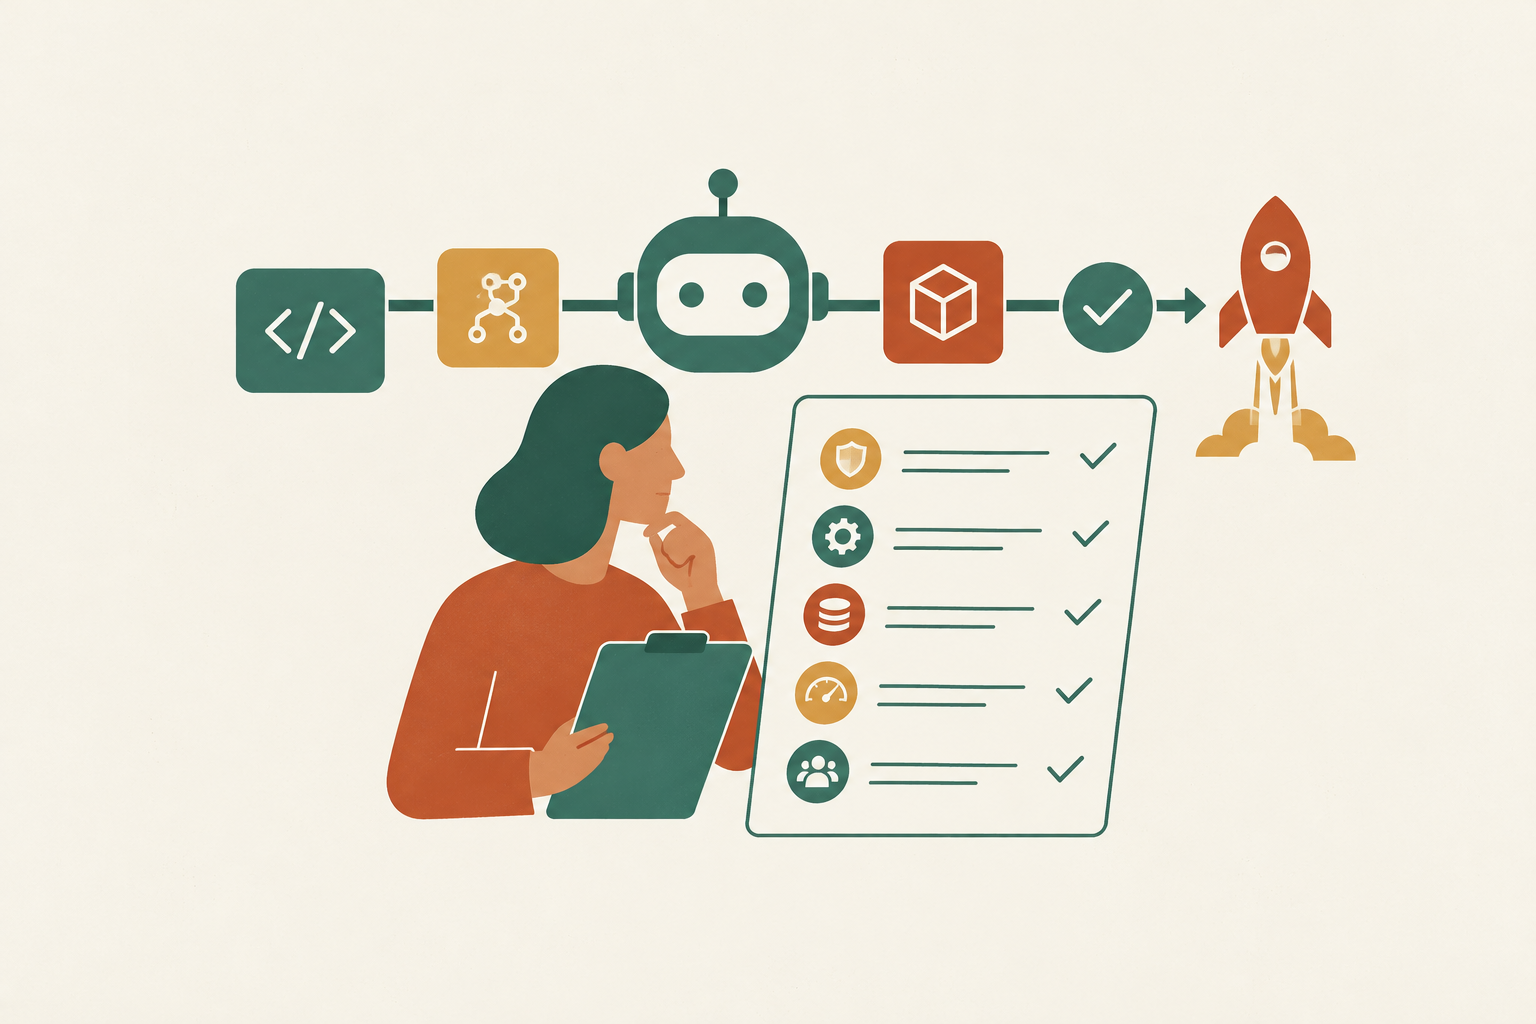
Production verification for AI-generated and agentic code requires more than passing CI tests. It requires real-traffic telemetry, staged canary gates, automatic rollback, and autonomous incident response within explicit governance boundaries. The right verification vendor connects these layers into a complete release-control loop, rather than assuming a human team can investigate every change before the next one reaches production.
Why agentic pipelines break the assumptions post-deploy verification tools were built on
OpenHands, Codex, Claude Code, Cursor, and Devin perform multi-step repository work, including implementing features, running tests, and submitting pull requests. The human role can narrow to specifying intent and reviewing outputs. Earlier gains in CI/CD speed still left time for a human to review before merge, while agent-speed pipelines can merge without one.
The Agile-V Assurance Spine paper cites a 2026 synthesis that distinguishes code production from production-qualified change. Review, integration, security, deployment, and operational evidence remain constraining stages, and agents do not automatically supply them. A generated patch, a passing test log, and an agent-produced review are not equivalent to an authorized release. Those outputs establish different things from permission to expose users to a change. Treating them as interchangeable leaves an assurance gap between an agent finishing its task and a system safely acting on the result.
That gap is also a coverage problem. CI tests verify code behavior in isolation, leaving system behavior under real traffic, real data distributions, concurrent users, and interactions across dozens of microservices unverified. Legacy post-deploy tooling assumed a human-paced cadence in which a team could investigate before the next deployment arrived. Agentic pipelines remove that breathing room without removing the need for evidence. The scorecard for choosing a verification vendor must therefore shift from detecting problems for people to investigate to using production evidence to act in time and within set bounds.
What agentic pipelines expose that existing tooling quietly ignores
Observability breakage is the first failure class. A new service can deploy without metrics being collected, logs flowing, or traces being generated. In that state, downstream verification has no reliable basis for declaring the deployment healthy. The missing signal is itself a deployment failure. A system that interprets silence as success cannot distinguish healthy production behavior from a broken instrumentation pipeline.
A service may produce metrics and logs while failing to propagate trace context across service boundaries. Async message queues are a common break point when message headers omit context, as are services using older SDKs that do not propagate the W3C TraceContext header. Local instrumentation can therefore look healthy even when cross-service correlation is impossible. The trace stops where the investigation needs to continue.
LLM-layer omissions create another form of partial visibility. Infrastructure metrics alone do not record token usage, model parameters, or prompt interactions, which OpenTelemetry’s GenAI semantic conventions bring into distributed tracing. Multi-agent systems add interaction-protocol failures and tool invocations with improper parameters or invalid configurations that can cascade silently. A supervisor agent checking for hallucinated dependencies across modalities is a pattern vendors have not yet standardized against.
Governance gaps make those technical failures harder to reconstruct. Without session-to-human identity mapping, an audit trail cannot reliably show who was responsible for an agent’s actions. Missing identity, logging, code review, and incident controls are weaknesses of their own, apart from model quality. They also complicate incident investigation after a technically successful deployment. An unstructured log may record activity without supplying the attribution security operations or auditors need.
Why real-traffic telemetry fidelity is the first and non-negotiable criterion
Production telemetry is the ground truth for post-deploy verification. Passing CI remains necessary, but it cannot establish how a change behaves under production conditions. Every later capability depends on the quality of that signal, including canary promotion, rollback, root-cause analysis, and remediation. A vendor cannot make up for weak ingestion just by using a stronger reasoning model. The first buying criterion is therefore the fidelity of the evidence.
In an evaluation, fidelity means ingesting traces, metrics, and logs and fusing them before reasoning. For complex microservice faults, this helps the system link symptoms across modalities instead of treating each signal as a story of its own. The vendor must also verify that observability works after every deployment. If instrumentation breaks, verification must treat the deployment as failed.
OpenTelemetry support alone is not a sufficient answer. Buyers should ask whether the vendor handles the GenAI conventions for token usage, model parameters, and prompt interactions, with opt-in events representing prompt interactions. They should also ask whether ingestion detects broken W3C TraceContext propagation at async boundaries. The required evidence connects AI performance to infrastructure cost and user latency without hiding breaks between services.
That evidence must distinguish canary traffic from its baseline. The mature sequence moves from deployment to a small canary traffic slice, synthetic monitors, contract checks, an SLO error budget check, and promotion or automatic rollback. The comparison must cover eval quality, latency, cost, and error rate against a recent baseline. Without cohort-aware telemetry, even a configurable gate lacks the evidence needed to judge the change it controls.
How to evaluate a vendor’s canary and rollback mechanics against agent-speed release cadences
A four-tier canary gate moves traffic through stages, checking eval quality, latency, cost, and errors at each tier. Its purpose is containment before broad exposure. A vendor that offers only binary deploy-or-rollback behavior cannot limit who is affected in the same stages. The practitioner pattern closes with a 72-hour runbook, rather than treating promotion as the end of operational responsibility. Evaluation should examine that complete sequence.
Rollback design must precede the first traffic shift. Kill switches, traffic-shift mechanics, and eval-driven rollback triggers belong on the pre-deploy checklist. A rollback that requires a human to initiate it under alert conditions restores the delay the agentic pipeline removed. Buyers should therefore examine both the trigger and the action it invokes. Detecting a threshold breach is not equivalent to containing it.
Gates also need to reflect the deployment type. Eval-only monitoring misses cost spikes, latency-only monitoring misses quality drift, and cost-only monitoring misses correctness regressions. A vendor with only latency and error-rate gates leaves the AI-specific axes unchecked. Feature-flag integration addresses a different requirement by separating deployment from release, so behavior can be gated per user, tenant, or workload. Without that separation, disabling a misbehaving feature can require a full redeploy.
Promotion needs to follow policy just as rollback does. At an agent-speed cadence, autonomous promotion must work within set bounds so that every successful canary does not have to wait for a human. This does not require unrestricted autonomy. The evaluation should establish which decisions the vendor can execute under policy and which remain subject to confirmation.
Autonomous incident response capability as a vendor differentiator, not a premium feature
Canary gating limits exposure, but response starts when a regression needs to be investigated and fixed. If pipelines merge multiple times per hour, a vendor whose workflow ends by alerting an on-call engineer recreates the human bottleneck. Autonomous response is therefore a baseline requirement for this release model. Vendors differ in how far they can safely take the work after detection.
Automated root-cause analysis is the entry requirement. It should correlate logs, metrics, traces, and deployment history, using specialized reasoning paths for different signal types. Its accuracy depends on structured ingestion, which makes the telemetry criterion inseparable from the response criterion. Missing context constrains what the system can establish.
The stronger differentiator is what follows the diagnosis. A vendor that identifies a regression and opens a fix PR for review without human initiation removes the need for an engineer to start the investigation workflow. Buyers should check whether the vendor can also handle instruction violations, prompt misinterpretation, and inter-agent protocol errors. Those failures need a different remediation vocabulary from a null pointer exception in a microservice. Generic claims about autonomous repair do not establish coverage of agentic behavior.
High-volume, low-actionability output transfers alert fatigue from monitoring to verification and leaves the work undiminished. The relevant comparison is the ratio of actionable to total alerts in reference customer environments.
Governance and audit trail requirements that most vendor evaluations skip
Autonomous response expands the importance of attribution because agents can initiate changes as well as diagnose them. A weak audit log is an operational liability whenever a team must reconstruct an incident. It also creates a compliance gap for organizations operating under SOC 2 Type II. Usable evidence must be preserved wherever agents have production write access.
The minimum record is centrally logged and queryable. It includes every agent-produced or agent-triggered file access, shell command, PR creation, API call, and deployment event. Keeping the records is not enough if security operations cannot search the activity or link related events. PRs that agents create should have labels that name the tool and session ID. That attribution lets investigators pivot from a proposed change to its originating session rather than searching an undifferentiated stream of actions.
Northflank’s enterprise deployment guide specifies that agent activity should flow into the enterprise SIEM, with retention meeting the applicable compliance framework’s requirements. A verification vendor must therefore meet the organization’s ingestion and retention needs even if it offers its own audit screen. Human oversight requires similar configurability. The vendor should show the boundaries between agent-autonomous decisions and those that need confirmation, so the choice goes beyond fully automatic or fully manual operation. Those boundaries make autonomous promotion and response compatible with organizational authority.
Secret detection belongs before merge on agent-produced PRs. Post-deploy verification still needs that pre-merge control, especially when the response system can itself change code. The vendor’s PR integration should include secret scanning as part of that boundary. Governance must cover the incident and the path back into production.
How should a team structure the vendor conversation around these criteria?
The buying process should test the integration surface before the feature demo. Begin by asking the vendor to show a canary deployment whose observability breaks partway through. Verification passes this test by catching the instrumentation failure and fails by reporting a clean deployment. Then request a walkthrough of broken W3C TraceContext propagation at an async message queue boundary. Together, these tests separate actual coverage from a dashboard that works only while its inputs remain intact.
Next, ask for LLM-layer evidence in the same investigation view. The vendor should show GenAI telemetry that links token usage, model parameters, and prompt interactions to infrastructure cost and user latency. Request a reference incident in which autonomous response produced a fix PR without human initiation, then examine whether the failure taxonomy includes prompt misinterpretation and inter-agent protocol errors. This establishes the supported scope without assuming that success on a service fault proves competence on an agent failure.
Security integration should happen before the contract is signed. Have the security team attempt to ingest the audit log into the existing SIEM, including the attribution needed to connect PRs to sessions. Commercial terms deserve scrutiny too. Ask how pricing changes if incident volume drops by half, and compare per-seat pricing with per-incident-resolved pricing against the outcome the team wants. The pricing model exposes what the vendor charges for, rather than proving its incentives through marketing language.
Finally, evaluate the full working loop, including detection, diagnosis, response, and verification of the fix. Every handoff to separate tracing, alerting, or response tools forces the team to move context while the SLO error budget is being consumed. A capable detector may still leave that workflow burden unresolved. The purchase decision should turn on whether the vendor can close the loop under real deployment conditions, with evidence and authority intact at each transition.